Turning a base LLM into a dependable, policy-aware assistant means running several fundamentally different kinds of training: supervised fine-tuning to teach format and instruction-following, then preference optimization or RL to shape tone, safety, and judgment. Most teams end up gluing together separate tools for each stage, each with a different config format and a different failure mode.
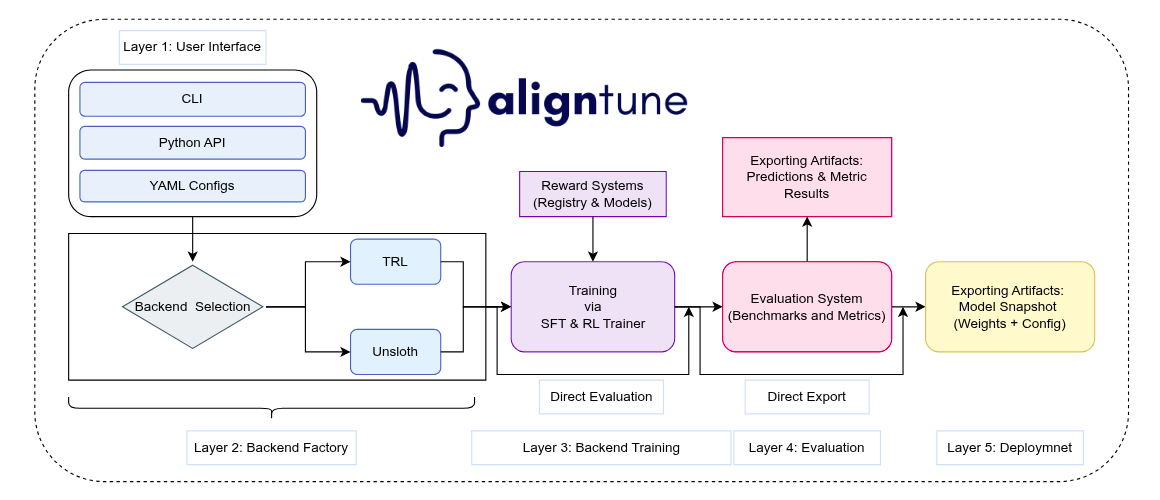
AlignTune treats this as one problem with a unified API. You configure a trainer, pick a backend, pick an algorithm, and run. The library abstracts the backend complexity away entirely, so switching from TRL to Unsloth (or back) is a config change, not a rewrite.
What's under the hood:
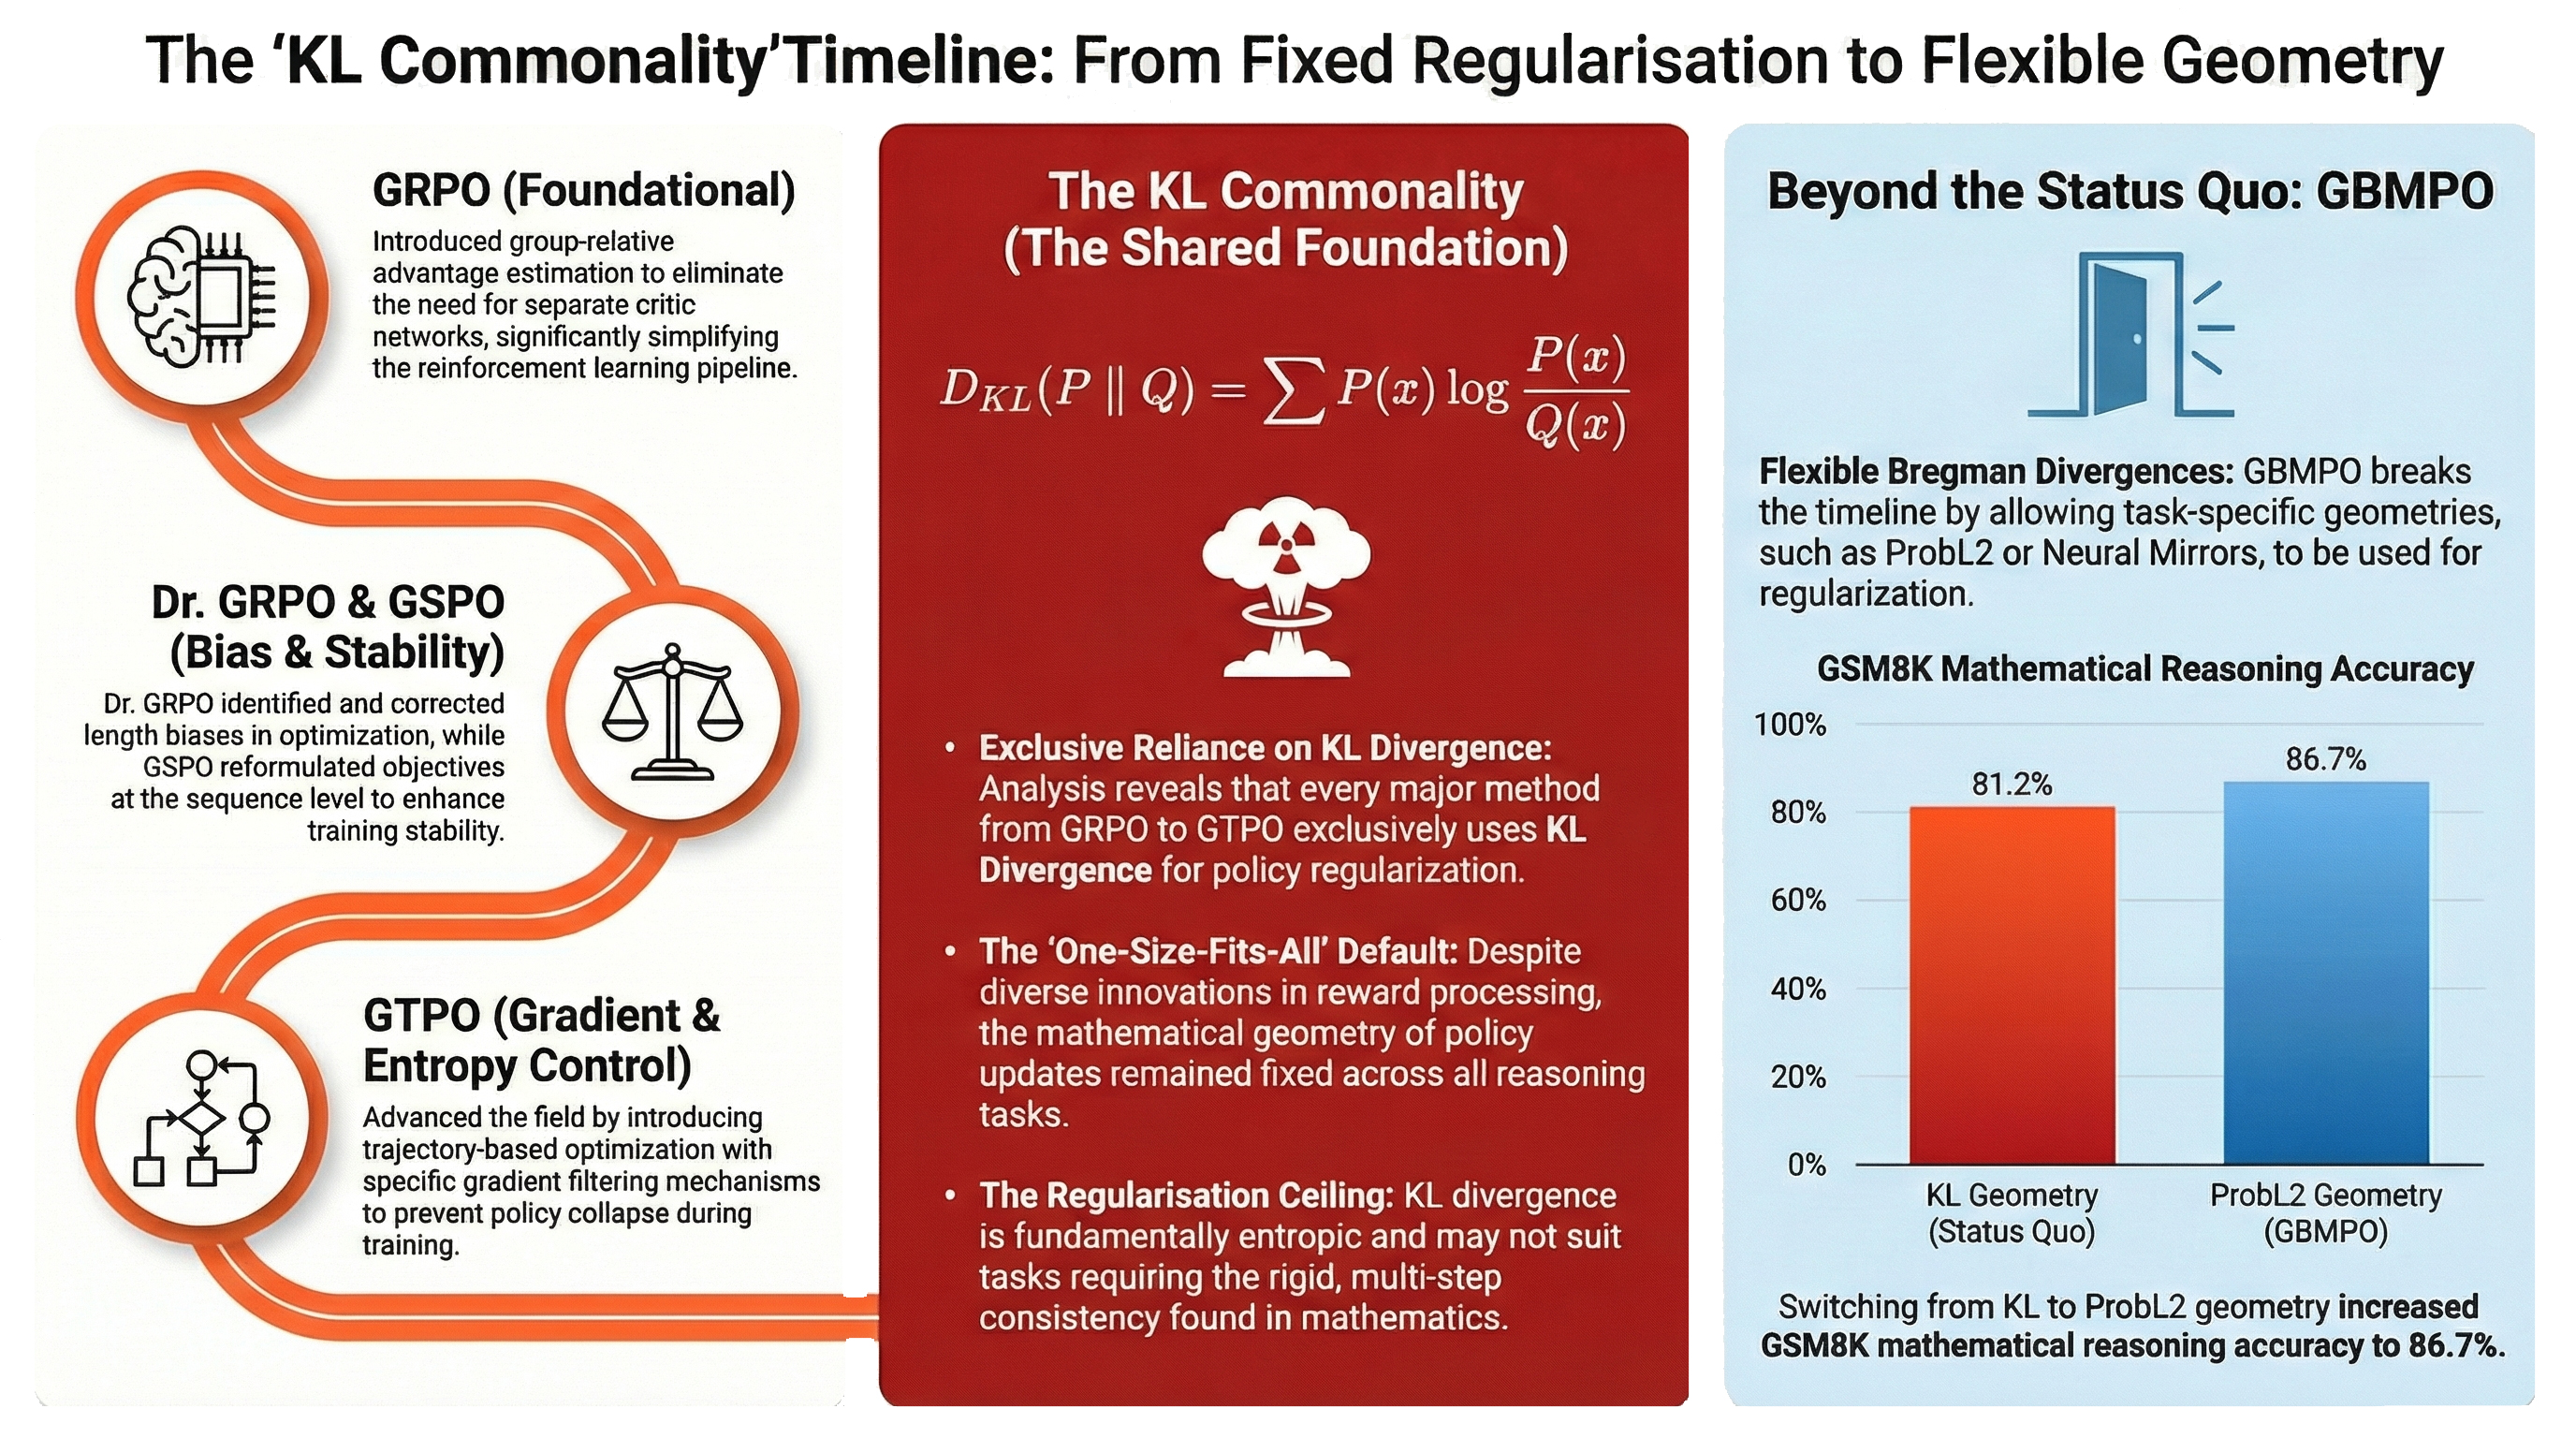
- 12+ RL and preference algorithms. DPO, PPO, GRPO, GSPO, DAPO, Dr. GRPO, GBMPO, Counterfactual GRPO, PACE, and more, all behind the same trainer interface.
- 30+ reward functions, ready to use out of the box, for steering tone, helpfulness, safety, and behavioral consistency, so you're not writing reward logic from scratch.
- Two interchangeable backends. TRL, for reliability, and Unsloth, for speed, with automatic fallback between them.
- Ready-to-run recipes. Configurable trainers and recipe templates built for repeatable, comparable experiments, not one-off scripts.
AlignTune is built for the research-to-production handoff: the same trainer config that runs a quick SFT experiment on a small model scales to a full alignment run, with comprehensive error handling and validation instead of the mock code you'd expect from a research-only tool.
Who it's for
- Teams running the full alignment pipeline (SFT through RLHF) who don't want to maintain four separate tools to do it.
- ML engineers who want to benchmark algorithms (DPO vs. PPO vs. GRPO, and so on) without rewriting the training loop each time.
- Anyone who's hit a wall with a single backend and wants to switch TRL and Unsloth without switching tools.
Links:
- arXiv: https://arxiv.org/abs/2602.09621
- Docs: https://aligntune.lexsi.ai/
- Research paper: https://lexsi.ai/resources/research-papers/aligntune-modular-toolkit-for-post-training-alignment-of-large-language-models
- License: source-available — free for research/non-commercial use; commercial use requires a separate license from Lexsi Labs
- Authors: R E Zera Marveen Lyngkhoi, Chirag Chawla, Pratinav Seth, Utsav Avaiya, Soham Bhattacharjee, Mykola Khandoga, Rui Yuan, Vinay Kumar Sankarapu (Lexsi Labs)